[ Machine Learning Development ]
Predictive Models That Move Revenue and Cut Losses
We build machine learning models that score churn risk, forecast demand, catch fraud and set prices, then wire them into the systems your team already uses. Every model ships with a feature pipeline, a holdout benchmark and drift monitoring.
- Products shipped across 14+ industries
- 100+
- Products shipped across 14+ industries
- Weeks to a validated first model
- 3 to 5
- Weeks to a validated first model
- Inception program member
- NVIDIA
- Inception program member
- Model, feature code and data ownership
- 100%
- Model, feature code and data ownership
Predictions Worth Building First
Good machine learning projects start where you already have history, a clear decision to improve and a cost attached to getting it wrong.
 Prediction 01
Churn and retention scoring
Account-level risk scores refreshed daily from product usage, billing and support signals, with the top reasons for each score so success teams know what to say.
Retention effort goes to accounts that can still be saved
 Prediction 02
Demand forecasting
SKU and location forecasts that account for seasonality, promotions, holidays and stockouts, feeding purchase orders and staffing plans instead of a spreadsheet.
Less dead stock and fewer empty shelves
 Prediction 03
Fraud and risk detection
Real-time transaction and signup scoring that combines gradient boosting, graph features and anomaly detection, with a review queue for borderline cases.
More fraud stopped with fewer good customers blocked
 Prediction 04
Dynamic pricing
Price elasticity models and guardrailed recommendation rules that suggest prices per product, market or customer segment, tested through controlled experiments.
Margin decisions backed by measured demand response
 Prediction 05
Recommendations and ranking
Two-stage recommenders with candidate retrieval and a learned ranker for products, content or listings, tuned to conversion rather than clicks alone.
Higher basket size and more relevant feeds
 Prediction 06
Lead and lifetime value scoring
Models that predict which leads convert and what a customer is worth over 12 months, so sales and paid acquisition spend where returns are highest.
Acquisition budget tied to predicted value
How a Production ML System Fits Together
We separate data, training and serving so each part can be scaled, audited and replaced on its own.
Data foundation
Warehouse · Event streams · Product database · Labels
The raw history the models learn from.
Features
Feature store · Streaming features · Data validation · Lineage
Reusable, point-in-time correct inputs shared by training and serving.
Training and evaluation
Training pipelines · Backtesting · Hyperparameter search · Experiment tracker
Builds candidate models and proves they beat the current one.
Serving
Model registry · Batch scoring jobs · Inference API · Shadow mode
Delivers scores in batch or in milliseconds, with versioned models.
Decision points
CRM fields · Checkout API · Ops dashboards · Alerts
Where predictions change what your product or team does.
The Engineering Behind a Reliable Model
A model notebook is the small part of the work. The rest is data, deployment and the loop that keeps it accurate.
- 01Feature engineering and stores
Point-in-time correct features defined once in a feature store, so training and serving use the same logic and leakage is caught early.
- 02Model development
Gradient boosting, deep learning and time-series methods compared on the same splits, with the simplest model that meets the target chosen.
- 03Honest validation
Time-based splits, backtests and segment-level metrics such as AUC, MAPE and precision at k, measured against your current baseline.
- 04Explainability
SHAP values and reason codes on every prediction, so analysts, regulators and customers can see why a score was given.
- 05Batch and real-time serving
Nightly batch scoring to your warehouse or low-latency APIs for checkout and signup flows, sized to your traffic.
- 06Monitoring and drift
Data drift, prediction drift and live accuracy tracked per segment, with alerts when inputs or outcomes move outside agreed limits.
- 07Retraining pipelines
Scheduled or triggered retraining with champion and challenger comparison, so new models replace old ones only when they win.
- 08Experiment tracking
Every dataset version, parameter set and metric logged, so any result can be reproduced months later.
Prove the Model on Your History First
A feasibility prototype trained on your own data, measured against the way you decide today, with a clear go or no-go before any production build.
Book the Feasibility Prototype- Prototype
- 2 to 3 weeks
- Prototype
- Your model and data
- 100%
- Your model and data
Teams That Act on Our Predictions
“I had the pleasure of working with Sajal Tech on a travel website, and it was an incredible experience from start to finish. They demonstrated professionalism, clear understanding of requirements, and excellent communication throughout.”
Machine Learning by Industry
Where we have built models that change a decision every day.
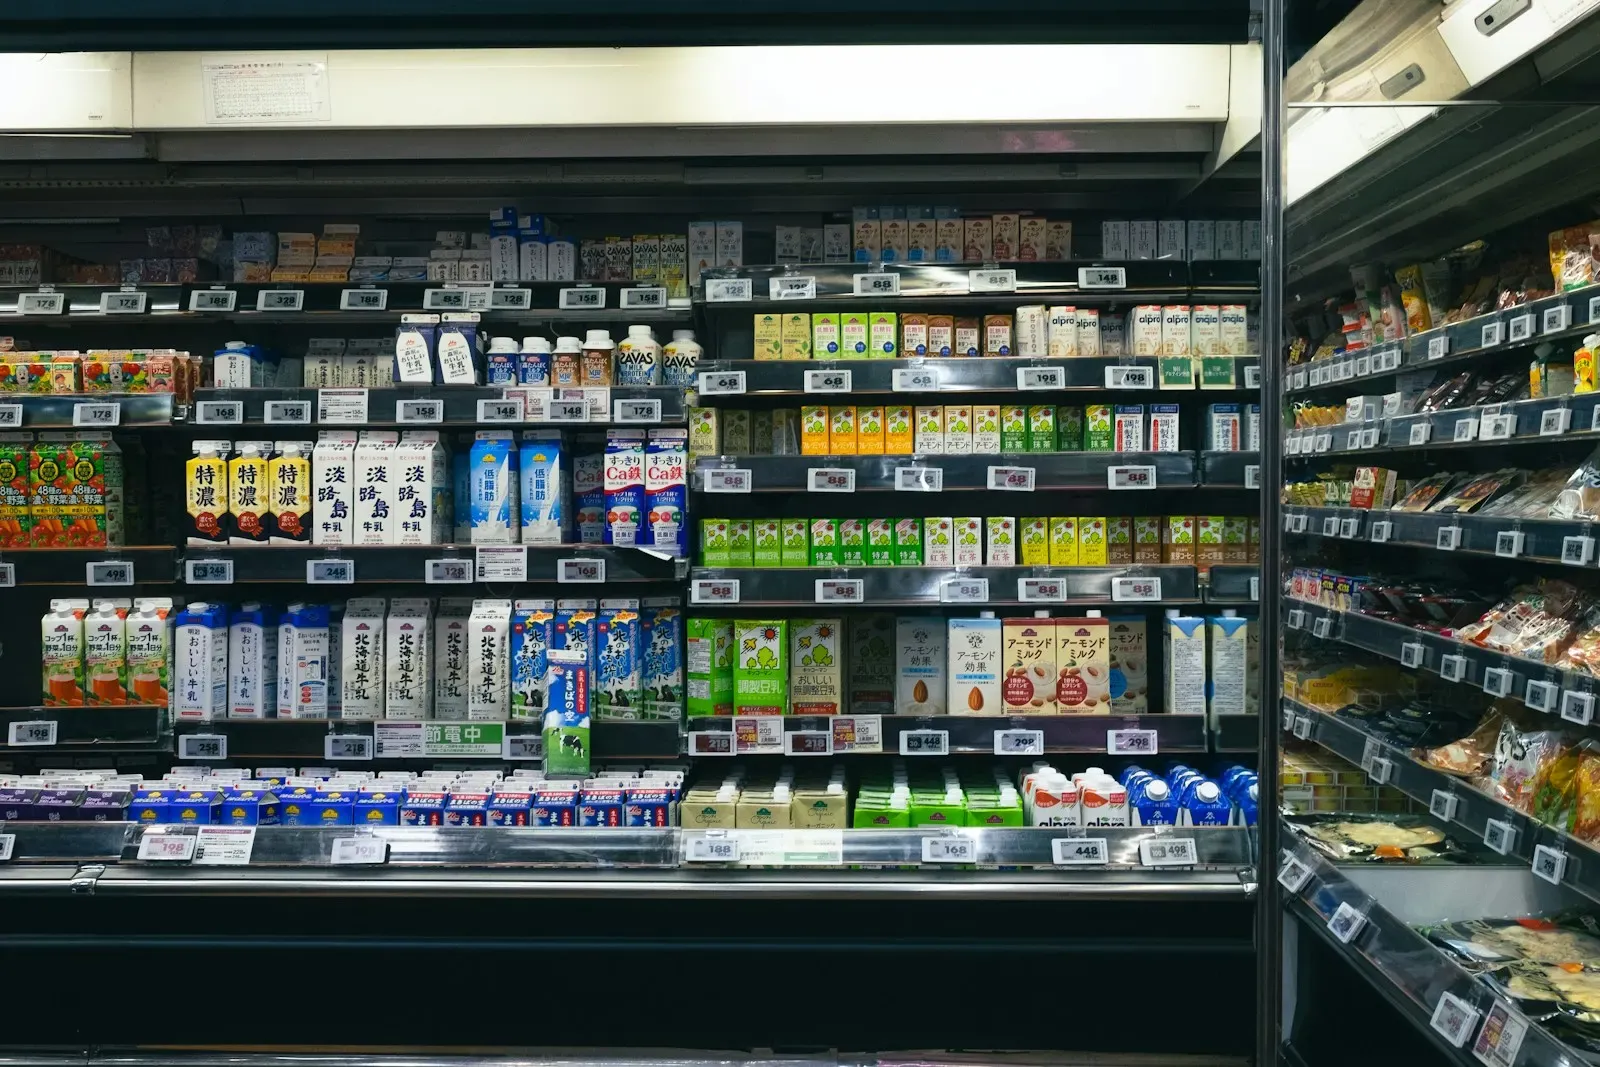
Store and SKU level demand forecasts, markdown pricing and recommendations trained on your sales, promotions and stock history.
- Demand forecasting
- Markdown pricing
- Basket recommendations
Retail and grocery
Models You Can Defend
Predictions that affect money or customers need to be fair, explainable and checked over time.
- 01Bias and fairness checksWe measure error rates across customer groups before launch and after every retrain, and remove proxy features that encode protected attributes.
- 02Leakage preventionPoint-in-time joins and time-based validation stop future information from inflating offline scores that later collapse in production.
- 03Explainable decisionsReason codes and model cards document what each model does, what data it uses and where it should not be trusted.
- 04Secure data handlingTraining runs in your cloud with masked PII and role-based access, delivered by an ISO 27001 and ISO 9001 certified team.
Libraries and Platforms We Use
We pick tools that fit your data volume and team. Most projects run on open-source libraries inside your own cloud.
- XGBoost
- LightGBM
- CatBoost
- scikit-learn
- PyTorch
- Prophet


From Historical Data to Live Predictions
We prove the signal exists before building the pipeline, so you do not pay for infrastructure around a weak model.
1 to 2 weeks
Data and baseline audit
Profile your data, define the target and success metric, and measure the rule or heuristic you use today.
- Data quality report
- Baseline metric
- Fixed quote
2 to 3 weeks
Model prototype
Feature engineering and model comparison on time-based splits, with results reviewed segment by segment in weekly demos.
- Validated model
- Backtest report
3 to 5 weeks
Production pipeline
Feature store, serving, monitoring and retraining built, then the model runs in shadow mode before it drives decisions.
- Live scoring
- Drift dashboard
- Runbook
Ongoing
Measure and retrain
A/B tests confirm business impact, and scheduled retrains keep accuracy steady as customers and markets change.
- Impact report
- Retrain log
Machine Learning Project Pricing
Indicative starting prices. Cloud compute is billed to your account, and we estimate training and serving costs up front.
Option 1
Feasibility prototype
One prediction problem tested on your historical data against your current baseline.
From
$2,500
Timeline
2 to 3 weeks
- Data audit
- Baseline and target model
- Backtest report
- Go or no-go recommendation
Option 2
Production model
A single model in production with features, serving and monitoring.
From
$12,000
Timeline
6 to 10 weeks
- Feature pipeline
- Batch or real-time serving
- Drift monitoring
- Retraining workflow
- 30 days of support
Option 3
ML platform
Shared feature store, registry and pipelines for several models and teams.
From
$35,000
Timeline
3 to 5 months
- Feature store setup
- Model registry and CI
- Multiple production models
- Team training
Machine Learning Questions
Still deciding? A 30-minute call usually answers the rest.
Ask Us DirectlyIt depends on the problem more than a fixed number. A churn model usually needs a year of history and a few hundred churn events, while fraud models need enough labeled fraud cases to learn patterns. Our data audit tells you within two weeks whether your data can support the model.
A feasibility prototype starts from $2,500, a single production model from about $12,000, and a shared ML platform from $35,000. Cloud compute is billed directly to you, and for most tabular models it is modest.
For predicting a number or a probability from structured data, such as churn, demand or fraud risk, classic machine learning is usually more accurate, cheaper and easier to explain. LLMs are better for language and documents. Many systems combine both.
We validate on time-based splits that mimic real use, backtest across past periods and compare against your current baseline. The model then runs in shadow mode on live data before it drives any decision.
Drift monitoring compares live inputs and outcomes against training data and alerts when they move. Retraining pipelines then build a challenger model, and it replaces the current one only if it performs better on recent data.
Yes. We attach SHAP-based reason codes to each score, such as falling usage or late payments, and provide a model card describing what the model does and its known limits. This matters for credit, insurance and pricing decisions.
Not for a single batch model. Once you have several models or need real-time features at checkout or signup, a feature store such as Feast prevents training and serving logic from drifting apart.
In your cloud, on AWS SageMaker, Google Vertex AI, Azure ML or plain containers. Batch scores can land straight in your warehouse or CRM, and real-time models sit behind an API with versioning.
You own everything: feature code, training pipelines, model artifacts and documentation. Your data team can retrain and extend the models without us, or we can run them on a monthly plan.
Let's build your next product together
Book a free strategy call and leave with a clear plan and estimate. No commitment.
- 01Pick a time that suits you
- 0230 minutes on scope, stack, timeline and budget
- 03Fixed-price proposal, NDA on request