[ AI predictive maintenance ]
Fix the Machine Before It Stops the Line
We build models on your sensor, PLC and maintenance history that spot the early signs of failure, estimate remaining life and turn warnings into planned work orders.
- Health score and remaining useful life
- Per asset
- Health score and remaining useful life
- Models run where your data lands
- Edge or cloud
- Models run where your data lands
- Warnings become planned work orders
- CMMS ready
- Warnings become planned work orders
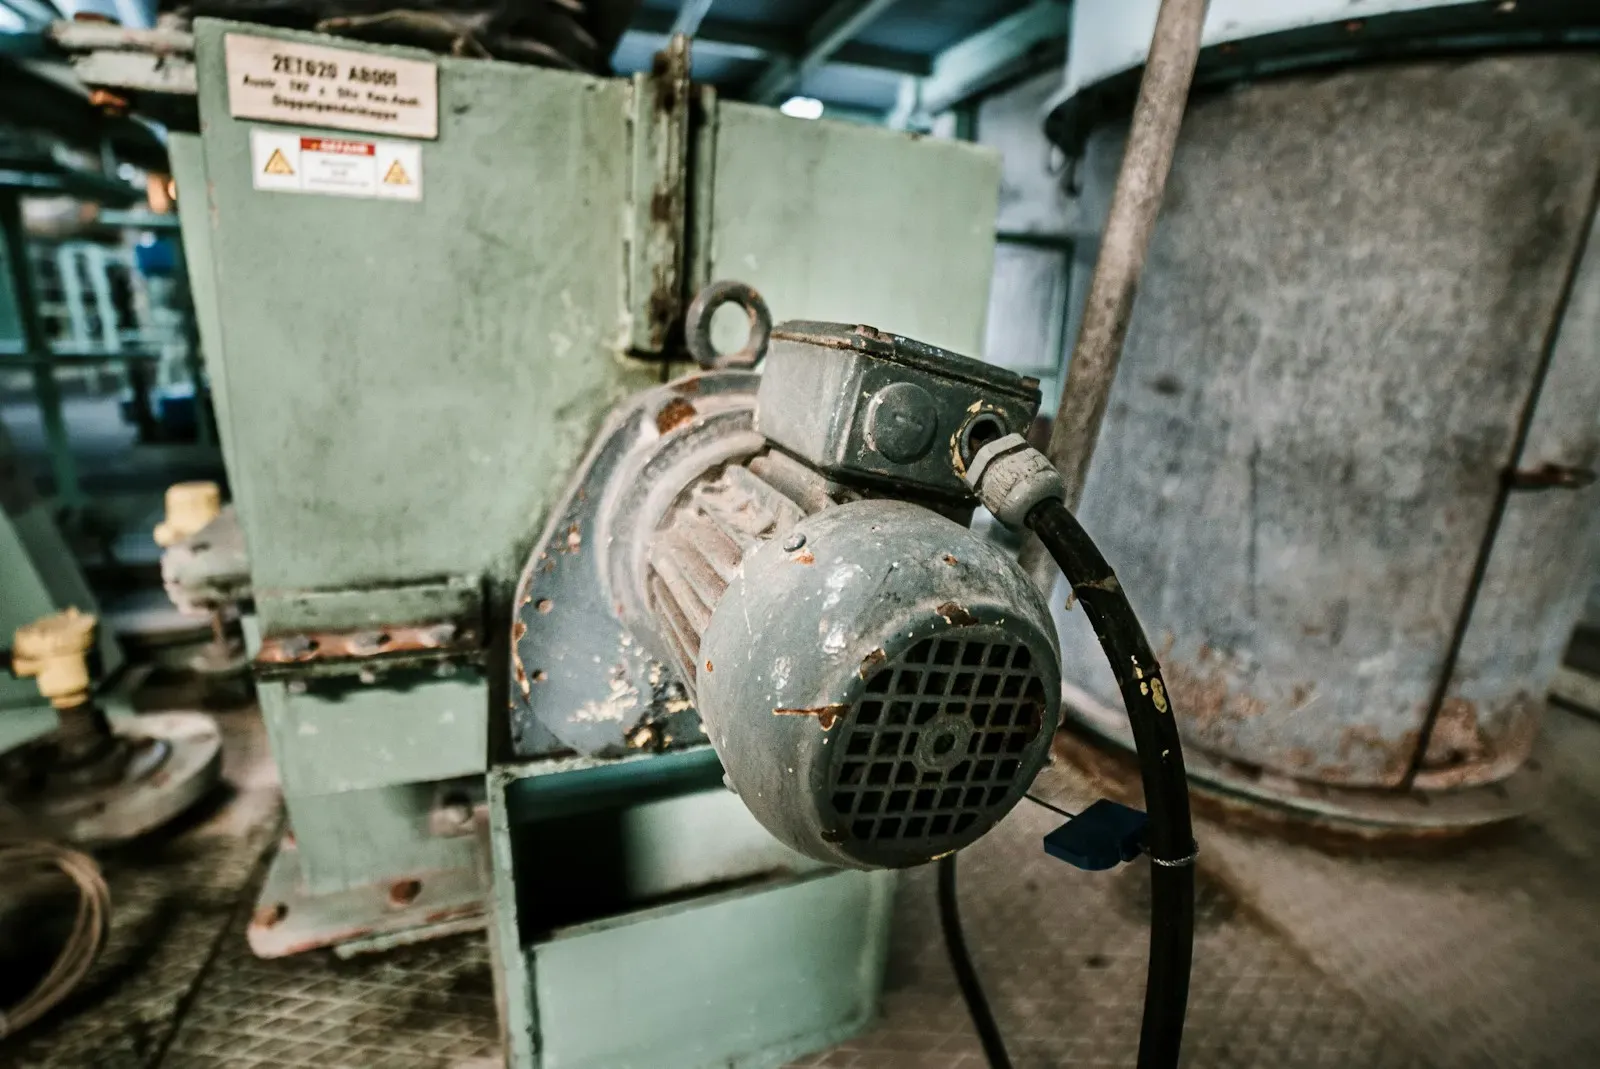
Motor M-14, vibration (example)
NormalRemaining life
41 days
Health
91%
Work order
None
Why Calendar Maintenance Wastes Money and Still Misses Failures
Fixed schedules replace healthy parts and miss the ones about to fail.
- 01
Unplanned stops
A single failed bearing or motor halts a line, a pump station or an aircraft.
- 02
Parts changed too early
Preventive schedules swap components with plenty of life left.
- 03
Data nobody reads
Sensors stream every second, but alarms only trigger when it is already too late.
- 04
Knowledge walks out
Experienced technicians retire, and their instinct for a sound or smell goes with them.
Data the Models Use
We map each source in the first weeks and only use the ones that improve the result.
- Vibration and acoustic sensors
- Temperature and pressure
- Motor current and power
- PLC and SCADA tags
- Work order and failure history
- Operating hours and load
How We Build Your Maintenance Models
We start with the assets that cost you most when they stop, and prove the model on their history.
- 01Asset and signal map
Asset and data review
We pick critical assets, map sensors, sampling rates and the failure records you already have.
- 02Time-series pipeline
Signal pipeline
Sensor and PLC data are collected through MQTT or OPC UA, cleaned and stored as time series.
- 03Validated models
Model build
Anomaly detection, failure classification and remaining-life models are trained and backtested on past failures.
- 04Live monitoring and alerts
Work order loop
Warnings go to a dashboard and your CMMS, and technician findings feed back into the model.
What the System Does
Designed for maintenance planners and plant engineers.
Sensor ingestion
Vibration, temperature, pressure, current and runtime from PLCs, SCADA or IoT gateways.
Where It Fits
What We Measure With You
Targets are agreed per asset class; results depend on sensor coverage and failure history.
- 01
- Warning lead time
- Days of notice before a confirmed failure
- 02
- Unplanned downtime
- Hours lost to unexpected stops
- 03
- False alarms
- Warnings with no fault found
- 04
- Maintenance cost
- Spend per asset per year
Prove It on the Machines That Cost You Most
We backtest on the assets with the most expensive stops first, then expand across the plant.
Book a Maintenance CallPredictive Maintenance Stack
Industrial protocols in, maintenance systems out.
Models
- PyTorch
- LSTM networks
- Isolation forest
- XGBoost
Ingestion
- MQTT
- OPC UA
- Apache Kafka
- AWS IoT
Storage
- InfluxDB
- TimescaleDB
- Amazon S3
Apps
- Grafana
- SAP PM
- IBM Maximo
- Power BI
Predictive Maintenance Cost
Indicative starting prices. Sensors and cloud usage are billed separately.
3 to 4 weeks
from$3,500
Asset feasibility study
Data review and a backtest on one asset class
8 to 12 weeks
from$15,000
Production monitoring
Pipeline, models, dashboard and CMMS link for one site
4 to 6 months
from$40,000
Multi-site rollout
Fleet monitoring across sites with edge deployment
What Plant Teams Say
Rated 4.9/5 on average across the platforms clients review us on.
 Clutch5.0
 GoodFirms5.0
- Google5.0
- Upwork4.9
I had the pleasure of working with Sajal Tech on a travel website, and it was an incredible experience from start to finish. They demonstrated professionalism, clear understanding of requirements, and excellent communication throughout.
Predictive Maintenance Questions
Still deciding? A 30-minute call usually answers the rest.
Ask Us DirectlyOften not. Many assets already report useful data through PLCs or SCADA. Where coverage is thin, we recommend the minimum extra sensors for the assets that matter most.
Yes. Anomaly detection learns normal behavior without failure labels, and failure-specific models are added as findings are recorded.
Yes. Models can run on edge gateways on site and sync results when a connection is available.
SAP PM, IBM Maximo, Fiix, UpKeep and custom systems through APIs or file exchange.
They see ranked warnings with the signals behind them, and record what they found, which improves future predictions.
Data stays in your network or cloud account. We follow ISO 27001 practices and work within your OT security policies.
Let's build your next product together
Book a free strategy call and leave with a clear plan and estimate. No commitment.
- 01Pick a time that suits you
- 0230 minutes on scope, stack, timeline and budget
- 03Fixed-price proposal, NDA on request