[ Vector Database Development ]
Vector Search That Stays Fast as Your Data Grows
We design, tune and migrate vector databases for semantic search, RAG and recommendations, choosing the store and index that fit your scale and budget. You get measured recall, predictable p95 latency and a clear monthly cost.
Example semantic search
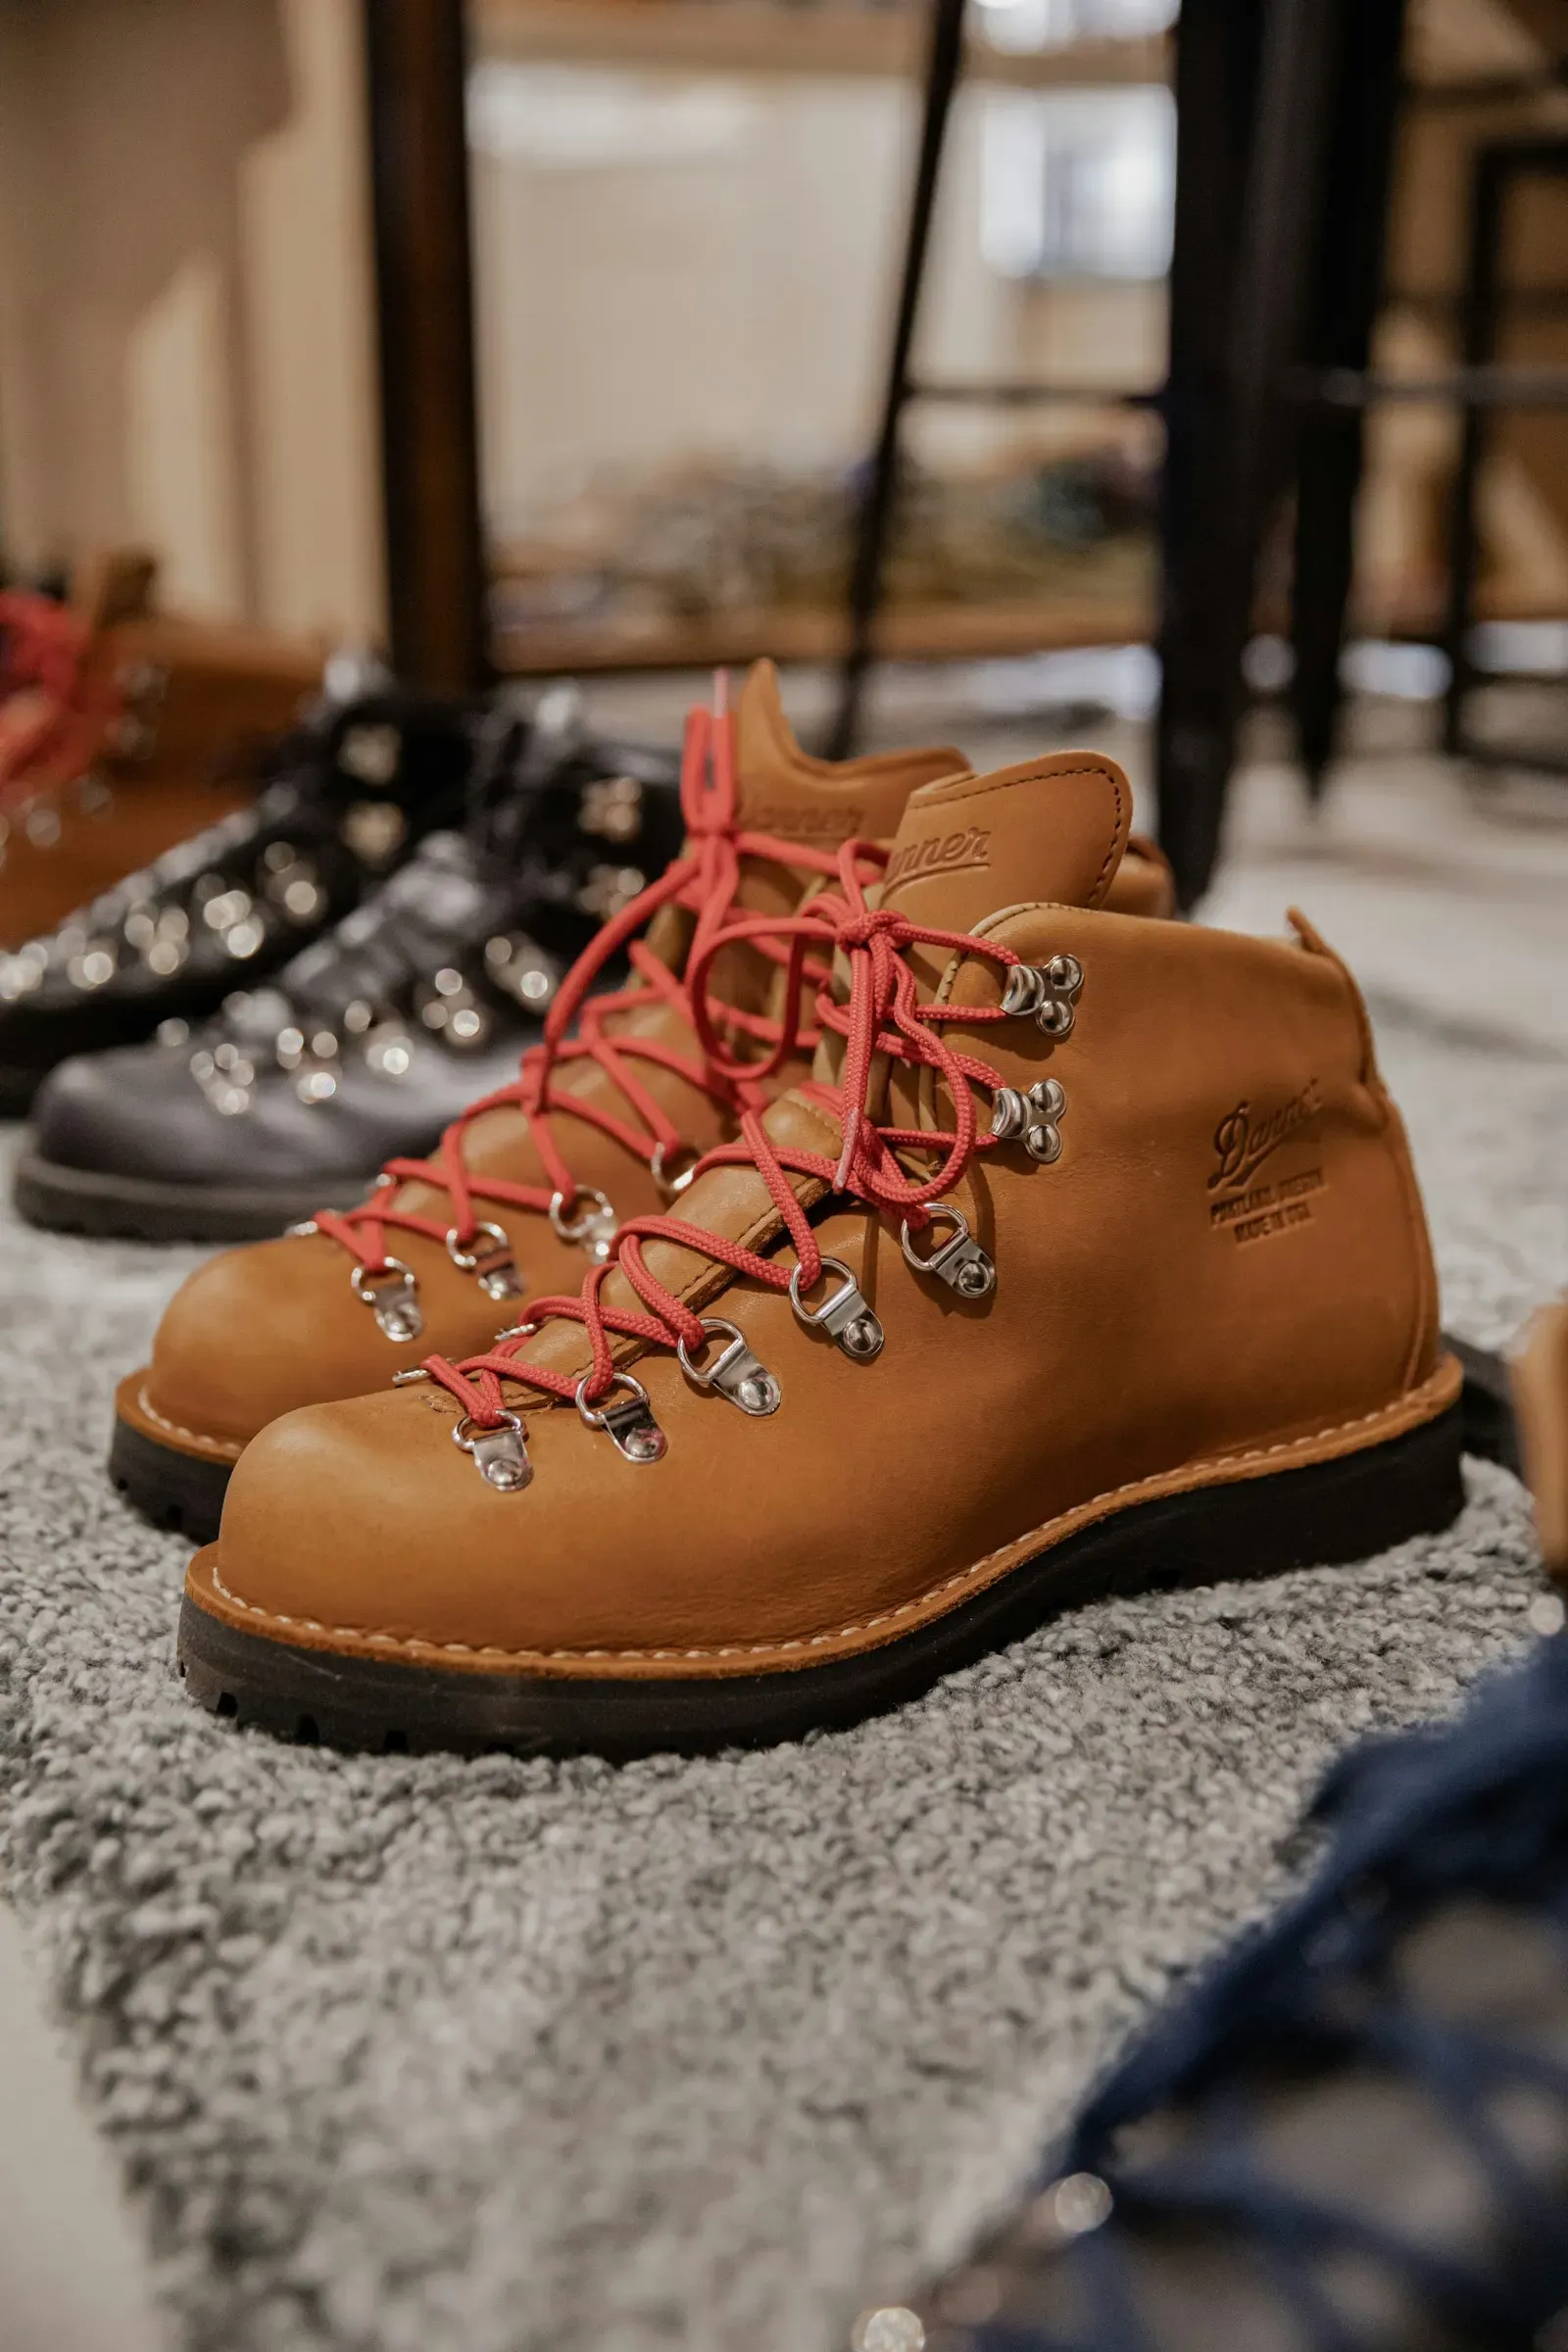 Leather hiking boot, wide fitSimilarity 0.92
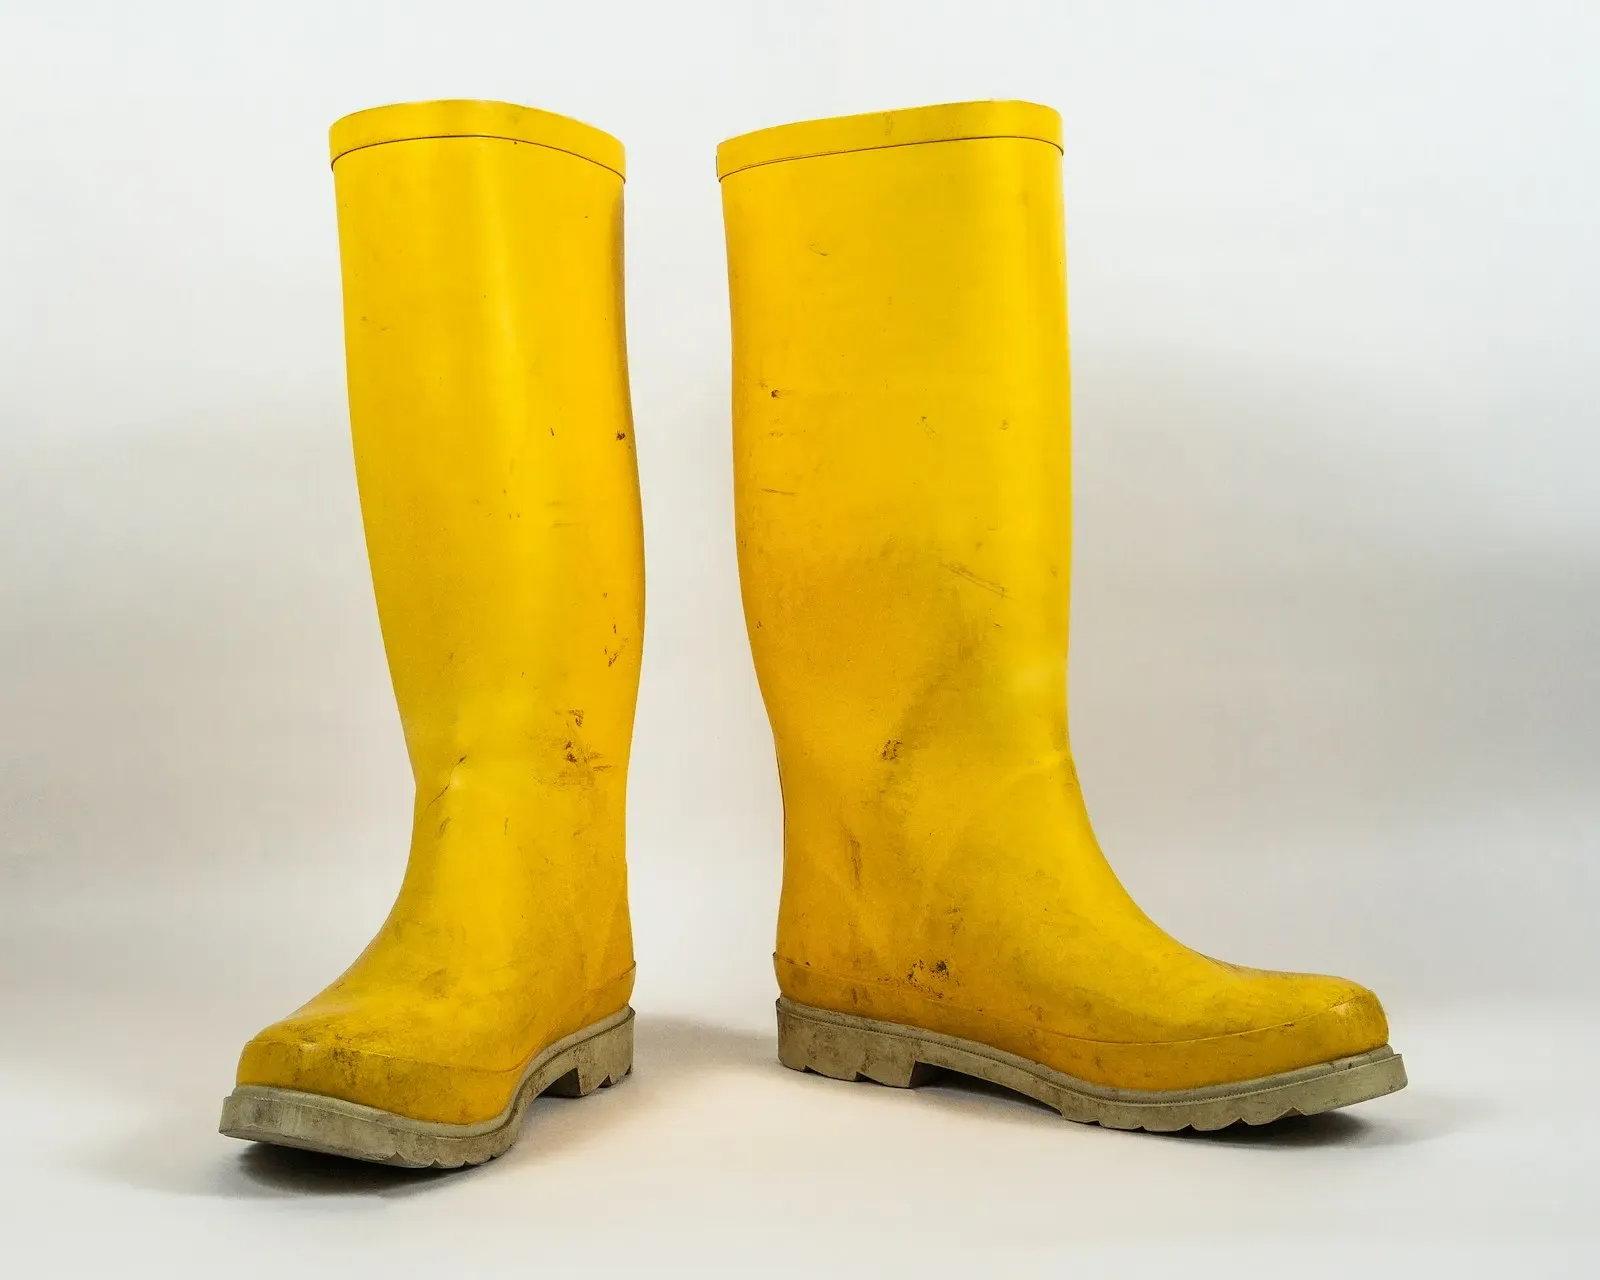 Waterproof rubber rain bootSimilarity 0.88
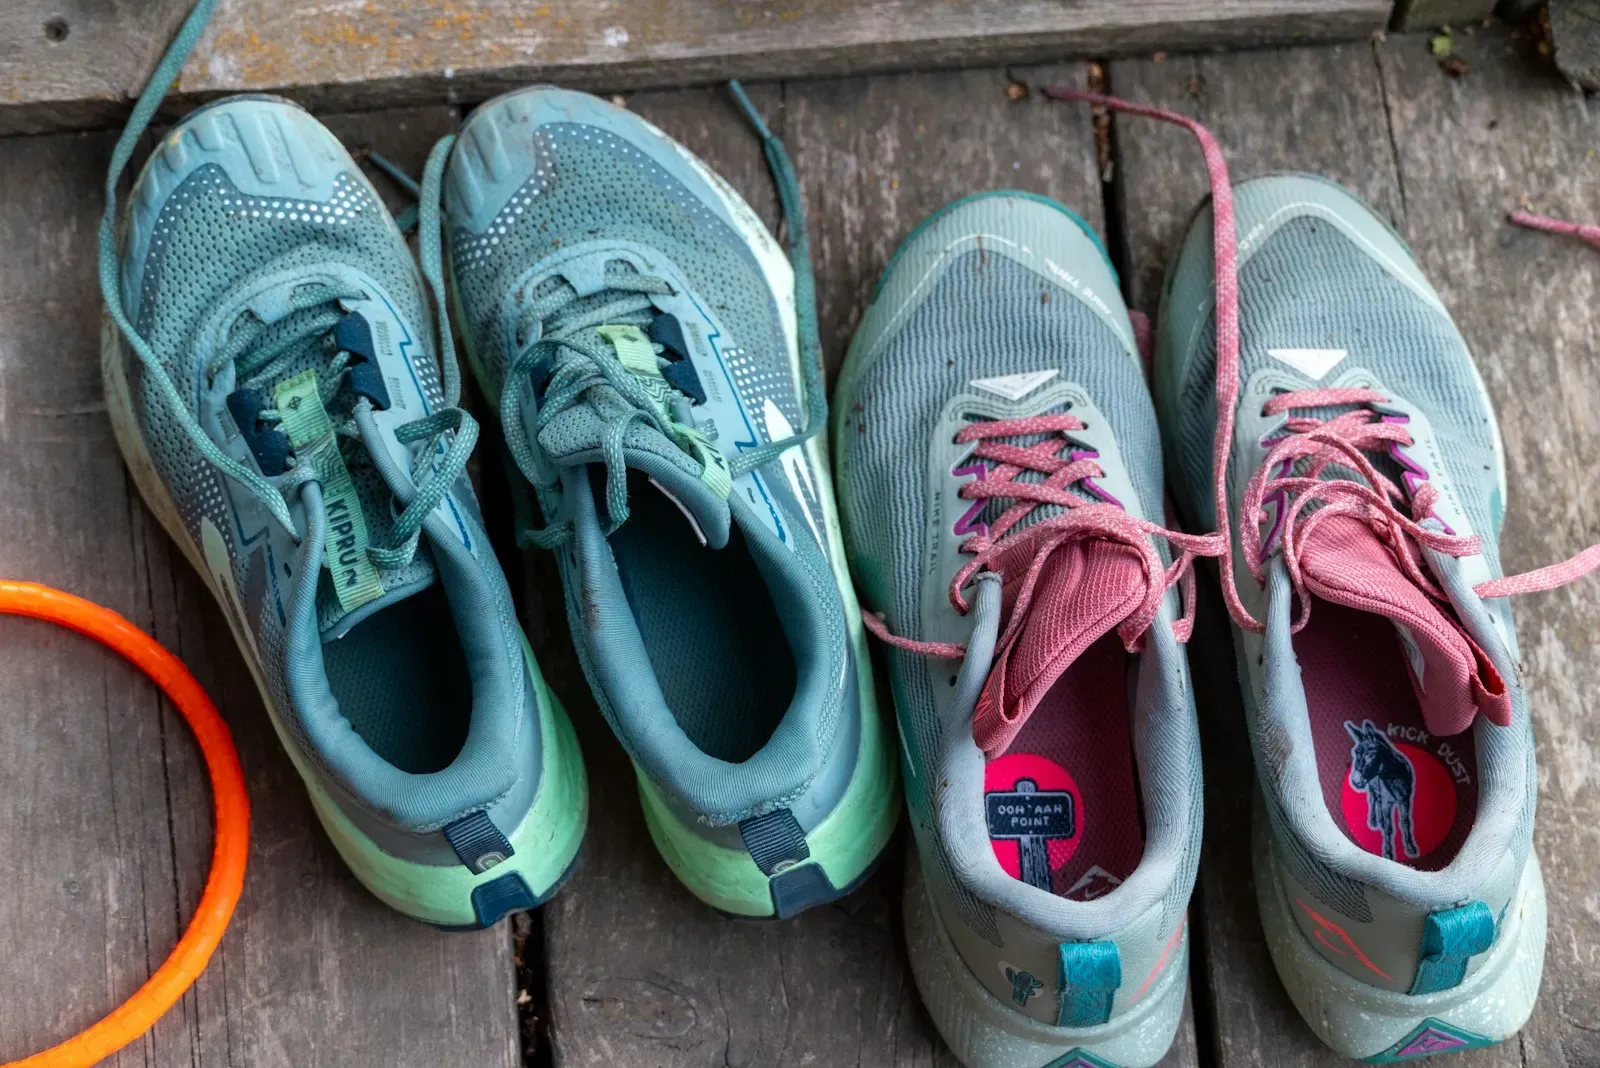 Trail shoe with a waterproof linerSimilarity 0.85
- Vector stores we deploy and tune
- 5
- Vector stores we deploy and tune
- To a benchmark on your own embeddings
- 1 week
- To a benchmark on your own embeddings
- Client retention
- 98%
- Client retention
- Certified security practices
- ISO 27001
- Certified security practices
Recall, Speed and Memory Pull Against Each Other
Every index setting trades one for another. Pick a setting to see the shape of the tradeoff, then we measure the real numbers on your own embeddings.
HNSW, balanced
The usual starting point
Illustrative shapes. Real values depend on your data, dimensions and hardware.
Problems a Well-Built Vector Layer Solves
Most teams reach for a vector database when RAG or search arrives. These are the moments it needs real engineering.
- 01
Search that slowed down with growth
Latency that was fine at one million vectors and painful at fifty, fixed with the right index, quantization and sharding plan.
Stable p95 latency as data grows
- 02
Vector bills growing faster than usage
Right-sizing pods and replicas, reducing dimensions, adding quantization and moving cold data to cheaper tiers.
Lower monthly cost for the same recall
- 03
Migration between stores
Moving from Pinecone to pgvector, Chroma to Qdrant or Elasticsearch to Weaviate, with dual writes, recall checks and no downtime.
Switch providers without a risky cutover
- 04
Semantic product search
Hybrid keyword and vector search over catalogs, with filters on price, stock and category applied inside the index.
Shoppers find items with natural phrases
- 05
Image and multimodal similarity
CLIP-style embeddings for visual search, duplicate detection and recommendations across images and text.
Similar items found in milliseconds
- 06
Multi-tenant SaaS retrieval
Per-customer isolation using namespaces, collections or row-level filters, so one tenant never sees another's vectors.
Safe retrieval for every customer
What We Engineer in the Vector Layer
A vector database is a search engine with tradeoffs. We make them deliberately and measure the result.
- 01
Store selection
pgvector, Pinecone, Weaviate, Qdrant or Milvus picked by scale, filtering needs, ops model and cost, based on a benchmark with your data.
- 02
Index design
HNSW, IVF-Flat, IVF-PQ or DiskANN chosen and tuned (m, ef, nlist, nprobe) for your recall and latency target.
- 03
Quantization and compression
Scalar, product and binary quantization with rescoring, cutting memory use while keeping recall within an agreed margin.
- 04
Sharding and replication
Shard keys, replica counts and tenant placement planned for throughput, failover and noisy-neighbor isolation.
- 05
Hybrid and filtered search
Sparse and dense vectors fused with reciprocal rank fusion, plus payload indexes so metadata filters do not wreck recall.
- 06
Zero-downtime migration
Backfill, dual writes, shadow reads and recall comparison before traffic moves to the new store.
- 07
Embedding pipelines
Batch and streaming jobs that embed new data, re-embed on model upgrades and keep vectors in sync with the source of truth.
- 08
Benchmarking and monitoring
Recall@k, QPS and p95 latency tracked against a ground-truth set, with alerts when index drift lowers quality.
Anatomy of a Production Vector Layer
We keep embeddings, storage and query logic separate, so you can change any one without rebuilding the rest.
Query API
01The search interface your apps and agents call.
- Search service
- Filter builder
- Hybrid fusion
- Result cache
Vector store
02Indexes and serves vectors with metadata.
- Collections or namespaces
- HNSW or IVF index
- Payload indexes
- Quantized vectors
Cluster and storage
03Capacity, durability and isolation.
- Shards
- Replicas
- Snapshots
- Tiered storage
Embedding pipeline
04Turns source records into vectors and keeps them fresh.
- Change data capture
- Embedding workers
- Batch backfill
- Version tags
A Benchmark on Your Own Embeddings
We load a sample of your vectors into two or three candidate stores and index settings, then report recall, p95 latency and monthly cost side by side.
Book the Vector Audit- Benchmark
- 1 week
- Benchmark
- Stores we deploy and tune
- 5
- Stores we deploy and tune
Vector Search by Industry
Where search by meaning, not keywords, changes what people find.
E-commerce
More on this industryHybrid product search with price, stock and category filters applied inside the index, so natural phrases find the right items.
- Semantic product search
- Visual similarity
- Filtered recall
SaaS products
Per-customer retrieval for RAG features, isolated by namespace or enforced filters and tested on every release.
- Multi-tenant RAG
- Tenant isolation tests
- Cost per customer
Media and publishing
More on this industryArchives of articles, images and clips searchable by meaning, with duplicate detection across sources.
- Archive search
- Duplicate detection
- Related content
Financial services
More on this industryResearch and document retrieval inside a private network, with deletion that removes vectors when records are removed.
- Research search
- Private endpoints
- Right to be forgotten
Vector Data Treated Like Production Data
Embeddings can be inverted to reveal source text, so we protect them like the records they came from.
- Tenant isolationSeparate namespaces or enforced filters per customer, covered by automated tests that try cross-tenant queries.
- Encryption and private networkingEncryption at rest and in transit, private endpoints or VPC peering, and no public exposure of the index.
- Deletion that actually deletesWhen a source record is removed or a user asks to be forgotten, the matching vectors and payloads are removed too, with a log to prove it.
- Recall regression gatesIndex parameter changes, quantization and embedding model upgrades only ship after recall@k is checked against a ground-truth set.
Clients on Working With Us
 5.0Clutch
 5.0GoodFirms
- 5.0Google
- 4.9Upwork
I had the pleasure of working with Sajal Tech on a travel website, and it was an incredible experience from start to finish. They demonstrated professionalism, clear understanding of requirements, and excellent communication throughout.
Knowledgeable, efficient, and ahead of schedule. Will hire again.
They completed our project even when the scope changed slightly. They were cooperative when we wanted to add or modify features.
Stores, Embeddings and Tooling
We are store-agnostic. Often the best answer is pgvector in the Postgres you already run, sometimes it is a dedicated engine.
Vector databases
- pgvector
- Pinecone
- Weaviate
- Qdrant
- Milvus
- Zilliz Cloud
Search engines with vectors
- Elasticsearch
- OpenSearch
- Redis
- MongoDB Atlas Vector Search
Embedding models
- OpenAI embeddings
- Cohere Embed
- Voyage AI
- BGE
- CLIP
Benchmarking and ops
- ann-benchmarks
- VectorDBBench
- Prometheus
- Grafana
- Terraform
How We Deliver a Vector Database Project
We benchmark on your vectors before choosing anything, then roll out behind a safety net.
3 to 5 days
Workload profiling
Measure data size, query patterns, filter use, latency targets and current spend, and build a ground-truth recall set.
- Workload profile
- Recall test set
1 to 2 weeks
Benchmark and design
Compare candidate stores and index settings on your own embeddings, then pick the design with the best recall per dollar.
- Benchmark report
- Target architecture
- Cost forecast
2 to 5 weeks
Build or migrate
Provision with infrastructure as code, run backfills and dual writes, and compare results before switching traffic.
- Production cluster
- Migration runbook
Ongoing
Tune and operate
Monitor recall, latency and cost, resize as data grows and plan re-embedding when better models arrive.
- Monthly health report
- Capacity plan
What Vector Database Work Costs
Indicative starting prices. Database hosting is billed to your accounts, and we forecast it before you commit.
Option 1
Vector search audit
Benchmark and tuning plan for an existing vector setup.
From
$1,500
Timeline
1 week
- Workload and cost profiling
- Recall and latency benchmark
- Index and sizing recommendations
- Written action plan
Option 2
Vector layer build
A new production vector store with pipelines, hybrid search and monitoring.
From
$8,000
Timeline
3 to 5 weeks
- Store selection benchmark
- Embedding pipeline
- Hybrid and filtered search API
- Dashboards and alerts
Option 3
Migration or scale-out
Zero-downtime migration between stores or sharding for large datasets.
From
$18,000
Timeline
5 to 10 weeks
- Dual writes and shadow reads
- Sharding and replication plan
- Quantization and cost tuning
- Cutover and rollback runbook
Vector Database Questions
If you already run Postgres and have up to tens of millions of vectors, pgvector with HNSW is often enough and keeps your stack simple. Dedicated stores like Qdrant, Milvus or Pinecone make sense for very large collections, heavy filtering, high QPS or when you want a managed service. We decide with a benchmark on your data.
Pinecone is fully managed and quick to start. Weaviate has strong built-in hybrid search and modules, Qdrant is fast with rich payload filtering and runs anywhere, and Milvus is designed for very large distributed deployments. Cost, hosting rules and your team's ops capacity usually decide it.
HNSW builds a graph that gives high recall and low latency but uses more memory. IVF groups vectors into clusters and searches only the nearest ones, which uses less memory and suits very large datasets, especially with product quantization. We tune either to hit your recall target.
An audit of an existing setup starts from $1,500, a new production vector layer from about $8,000, and a migration or scale-out from about $18,000. Hosting costs depend on vector count, dimensions and replicas, and we forecast them before you commit.
Yes. We backfill the new store, run dual writes, compare results with shadow reads and only switch traffic once recall and latency match or beat the old system. A rollback path stays open until you sign off.
Quantization, smaller or truncated embedding dimensions, right-sized replicas, tiered storage for cold data and removing duplicate vectors usually give the biggest savings. Each change is checked against recall so quality does not quietly drop.
Vectors from different models are not compatible, so everything must be re-embedded. We version embeddings, build the new index in parallel and switch once it passes the recall tests, so search stays online throughout.
Filters applied after the vector search can return too few matches, and filters without an index are slow. Payload indexes, pre-filtering support in the engine and partitioning by common filters such as tenant usually fix both problems.
Let's build your next product together
Book a free strategy call and leave with a clear plan and estimate. No commitment.
- 01Pick a time that suits you
- 0230 minutes on scope, stack, timeline and budget
- 03Fixed-price proposal, NDA on request